On this page
AI training ROI is the question finance asks after the first programme: what did we get for it? "How many people finished" is easy to count; "what changed in their work" is harder. This article sets out what you can measure honestly, what you should refuse to claim, and how to report it. It is written for teams buying enterprise AI training for hundreds or thousands of people.
The short version: do not promise a single ROI percentage. Pick a few indicators that show skill and use, fix a baseline before you start, compare groups where you can, and report with the limits stated.
What each number can and cannot tell you
Completion rate
- People reached the end
- Not what they can now do
Checked result
- Something was produced
- The output can be reviewed
- Shows skill, per learner
Our framing, not a measured figure.
Why completion rates mislead
A completion rate tells you that people reached the end of a course. It does not tell you that they can do anything new. A video can be finished while the person is doing something else, and a quiz can be passed by recognising the right answer without ever using an AI agent on real work.
Satisfaction scores have the same limit. They show whether people liked the training, which matters for uptake, but not whether their work changed.
Usage numbers are better, yet still partial. Logins to an AI tool show that people opened it. They do not show whether the output was good, checked, or used. For a wider view of what organisations report on adoption, see our AI adoption statistics article.
The four levels of evidence, adapted to AI
The Kirkpatrick Model is a frame for training evaluation. It has four levels: reaction, learning, behavior and results. It works for AI training if you decide, per level, what counts as evidence.
Four levels of evidence for AI training
- ReactionFound it relevant? Cheap, weak proof
- LearningCan they do the task with an agent?
- BehaviorDo they use AI at work, with checks?
- ResultsDid a measure you chose before move?
Levels from the Kirkpatrick Model; the notes are our adaptation.
- Reaction: short survey on relevance ("will you use this in your job?"). Cheap, and a weak proof on its own.
- Learning: a task done with an agent, judged on the result. Practice leaves an output, so the result can be checked.
- Behavior: AI use in real work, on tasks you named in advance, with a review step. Ask managers, and sample actual work.
- Results: one business measure you chose before training began, such as turnaround time for a document type or rework rate on a report.
Levels 1 and 2 are the easiest to collect. Levels 3 and 4 take planning, which is why they are worth discussing with finance before launch rather than after.
Indicators that show skill
Skill shows up in what people produce, not in what they watch. Three indicators come out of practice-based training.
Milestones met on a real result. In a hands-on session, a learner must produce something (a page, a file, an agent that answers correctly) and the result is checked. At Tokenacademy, each employee practises with a real AI agent on a real project in the browser, and milestones are validated automatically on the result (the page, the files, the agent's replies). The share of learners who reach each milestone says more about skill than the share who clicked "next".
Repeat attempts. When a learner does a session again, do they get to the result more directly? An improving second attempt shows learning that carries over. A learner who repeats but does not improve shows where the coaching is needed. Track attempts per person, and the change between the first and the latest.
Request quality. Compare the first and the last request a learner writes for the same kind of task. A request that states context, task, guidelines and constraints is done once; a vague one gets redone. Those four parts (context, task, guidelines, constraints) can serve as a scoring grid on a sample of requests. The exercises that practise each of the four parts give you the requests to score.
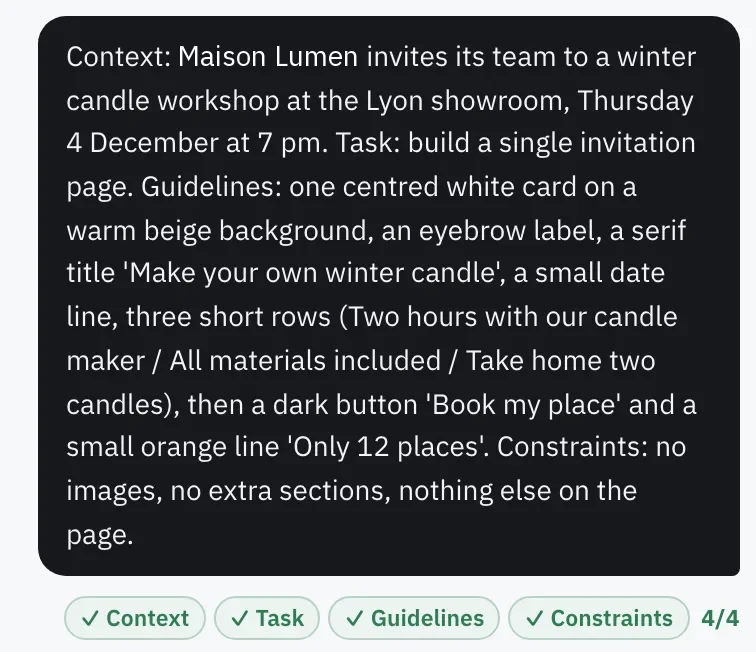 A request written in four parts, each ticked, 4 out of 4: a grid you can reuse to score a sample of requests.
If your platform connects to your learning system, completion and results per learner and progress by team can be sent back to it, so these indicators sit next to the HR data you already hold.
Effort per result: a metric you can track yourself
AI tools use measurable resources: tokens, time, retries. You do not need a vendor's benchmark to use that idea. Choose one recurring task, such as summarising a customer file, and record what it takes your people to reach an acceptable result before and after training: how many attempts, how long, how much of the tool's allowance.
Fewer attempts for the same quality is a skill indicator. It is also a cost indicator, because a request that is redone is paid for twice. Use your own tool's usage reports, or the free token counter to see how long a text is in tokens. The same text can count differently from one language and one model to another, so compare like with like. See why the count changes between languages and models.
Do not turn this into a cost-saving claim. Efficiency per result tells you how well a person uses the tool; it does not tell you what the business saved.
Isolating the effect of training
People improve with experience, tools get better, and a busy quarter distorts every number. To say that training made the difference, compare against a group that has not been trained yet.
The simplest design is a staggered rollout: train one cohort first, and measure both cohorts on the same indicators over the same weeks. A well-known example of staggered introduction is the NBER study Generative AI at Work, which followed 5,179 customer support agents and found that access to an AI assistant raised issues resolved per hour by 14% on average. Note that it studied access to a tool, not training, and its result belongs to that setting. It shows a method, not a number to expect.
A staggered rollout, step by step
- Fix the baselineSame indicators, both groups, before training
- Train cohort A firstCohort B waits, same work
- Re-measure bothAt 30, 90 and 180 days
- Train cohort BReport the gap, with its limits
Method sketch; the NBER study introduced an AI tool in a staggered way.
Choose the indicators in advance, so you cannot pick the flattering ones later. A small version of this design is an eight-week pilot with a baseline and a comparison group.
An AI training ROI reporting template
One page is enough for finance. Keep to four columns.
| Level | Indicator | Baseline | Now |
|---|---|---|---|
| Reaction | Relevance score | n/a | |
| Learning | Milestones met on a real result | ||
| Behavior | Reviewed work using AI, sampled | ||
| Results | One business measure, chosen up front |
Under the table, add three lines: what you did not measure, what else changed in the period, and what you will measure at the next checkpoint. A report that states its limits is easier to defend than one that does not.
If you are also asked about compliance, the EU AI Act's AI literacy requirement concerns measures taken, not a score; keep that evidence separate from the ROI story. To plan the programme itself, see how to train employees on AI, and for the formats compared, AI training formats. For how hands-on practice leaves a result you can check, read AI sandbox training.
What not to claim
- A single ROI percentage from a short period. Gains from AI take time to show and are shared with other changes.
- Time saved, estimated by the learners. Self-reports are useful as a signal, not as a financial figure.
- Causation without a comparison group. Say "associated with" if you have none.
- Vendor figures as your own. Another organisation's results do not transfer.
Where Tokenacademy fits
Tokenacademy is hands-on AI training for companies. Employees work with the real agents they will use at work, and each session leaves a result that was checked, which gives you evidence for level 2 of the table above (learning). It does not replace the business measure you choose; that stays yours. If you want to see what the evidence looks like for a team, book a demo.
FAQ
How do you calculate AI training ROI?
The usual formula is (gains minus training costs) divided by training costs. The difficulty is the gains: they must be a business measure you fixed before training and compared against a baseline or a group not yet trained. If you cannot do that, report leading indicators instead of a percentage.
How long before you can see results?
Re-measure at the checkpoints in the rollout figure above (30, 90 and 180 days). Skill indicators move first; business results usually lag them, and a single early reading can mislead.
Are usage numbers enough to prove AI training ROI?
No. Logins and licence use show that a tool was opened, not that the work improved. Pair adoption metrics with checked results.
Sources
- The Kirkpatrick Model, Kirkpatrick Partners: the four levels of evaluation (checked 2026-11-15).
- Generative AI at Work, NBER Working Paper 31161: 5,179 support agents, staggered introduction of an AI assistant, +14% issues resolved per hour on average (checked 2026-11-15).